Jipei He

Undergraduate at Renmin University of China

Portrait of Jipei He

What should a language model compute now to reason better later?

I started with latent reasoning. I now want to understand how pretraining can teach models to reuse their internal states, using looped Transformers to study when that reuse helps.

Selected Publications

STAIR First author arXiv preprint, 2026

Can Computation from Earlier Problems Help LLMs Solve New Ones?

Jipei He, Wenhui Tan, Xiaoyi Yu, Enver Sangineto, Fiorenzo Parascandolo, Rita Cucchiara, Ruihua Song

STAIR learns to read attention states saved from earlier answers, keeping the backbone and the saved states fixed.

On AIME 2025 with Qwen3.5-4B, STAIR improves mean later-turn accuracy (Avg@4) by 11.67 percentage points over the unmodified model with conversation history, using just 12,288 trainable parameters.
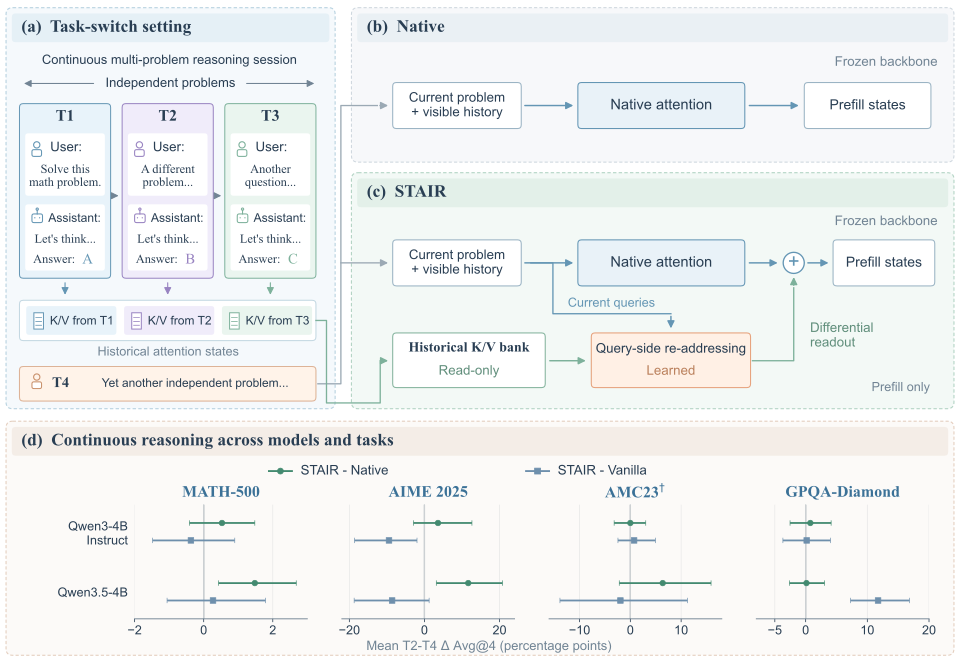
STAIR task switching, historical attention readout, and accuracy comparisons
STAIR method and results · CC BY 4.0

Research Direction

Looped Transformers let us vary how much computation happens between tokens without changing the parameter count. I want to understand when an extra step helps later predictions, even when the immediate token choice stays the same.

That puts the focus on pretraining: what kinds of dependencies in training data teach a model which intermediate states to keep and when to use them?

Research Experience

Started collaborating with Prof. Enver Sangineto.

University of Modena and Reggio Emilia

Joined AIMIND Lab as a research assistant, working with Prof. Ruihua Song.

Gaoling School of Artificial Intelligence, Renmin University of China

Started collaborating with Prof. Suyun Zhao.

School of Information, Renmin University of China